Tier 0 · Self-Serve Diagnostic Tool

RankTalos Findability Score

Enter your store URL. In 60 seconds we test 8 catalog-grounded shopper requests against your live search, compute 4 retrieval engineering sub-scores (0–100), and show a side-by-side preview of what our Talos Semantic Engine returns on your failed queries.

High / Partial Confidence Gated Zero false positives: a query is only marked Failed when your own catalog data contradicts the result. Includes a 24h Principal-Verified Snapshot option.

Free, 30–90 seconds. Polite sequential requests (max 60 total). Scanner details.

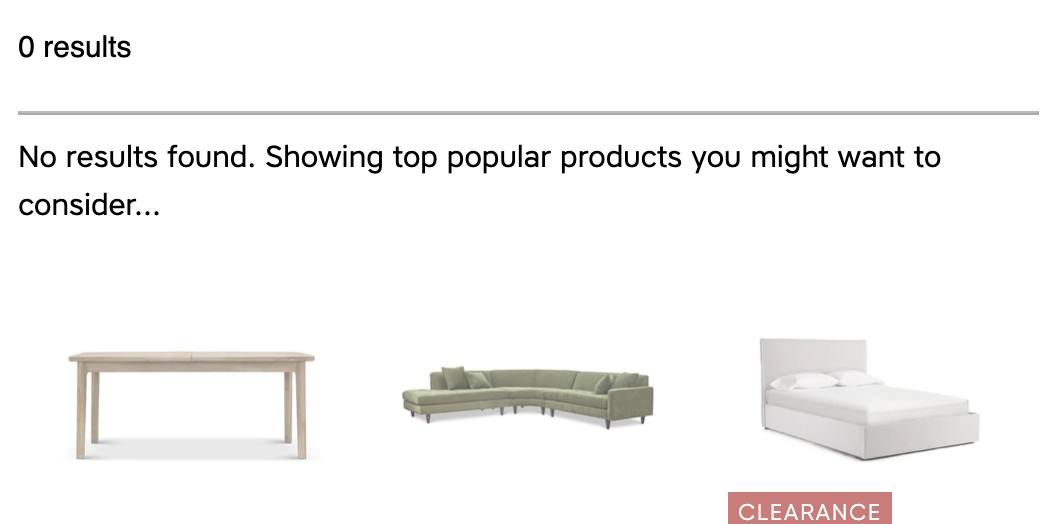
No results
A furniture store’s search page reading 0 results and “No results found. Showing top popular products”, above a dining table, a sectional sofa and a bed.
Furniture retailer A, October 31, 2026: 0 results on Fast Simon while 10 stands ≥67" wide are in stock. Talos Semantic Engine resolves all 10 in <90ms.

The 4 Engineering Sub-Scores (0–100)

How your Findability Score is calculated

Every report decomposes your 0–100 score across four retrieval and catalog engineering dimensions, paired with an explicit Engine Confidence Badge (High vs. Partial — JS Widget Detected).

Weight: 30%

1. Semantic & Constraint Recall

Numeric size/fit limits ("sofa under 80 inches"), price ceilings ("oak desk under $500"), material + attribute combinations, use-case ("good for kids and dogs"), and negation ("isn’t leather").

8 catalog-grounded queries where ≥ 2 in-stock items match; measures whether matching items appear in top 6 without zero-result failures.

Weight: 15%

2. Ranking Precision & Honesty

Top-3 precision on multi-constraint queries and zero-result honesty check (does the engine admit 0 matches or silently dump unrelated best-sellers?).

Top-3 relevant matches divided by judgeable top-3 slots, with penalty for silent popular-product fallback grids when matches exist.

Weight: 30%

3. Catalog Attribute Coverage

Structured vs. prose attribute extraction across top catalog categories (dimensions, materials, capacity, compatibility, SKU/GTIN).

Full credit (1.0) for attributes in structured options/tags/fields; half credit (0.5) for facts buried only in HTML prose; 0 for missing.

Weight: 25%

4. AI Crawler & Schema Readiness

schema.org/Product JSON-LD completeness (price, availability, brand, variants, MPN/SKU, physical dimensions), XML sitemap, and robots.txt access for OAI-SearchBot, PerplexityBot, Googlebot, and Bingbot.

100-point rubric: JSON-LD (25), physical specs (15), offers (15), brand (10), variants (10), IDs (10), AI search crawlers (10), sitemap (5).

Talos Semantic Search Side-by-Side Preview

See how our hybrid semantic engine parses constraints vs. keyword search

Inside every scan report—and live on our 10,000-SKU reference showcase at usafurnish.com—we compare your current lexical/widget search against the Talos Semantic Engine:

Talos Semantic Engine constraint parsing preview
Shopper Constraint QueryLexical / Keyword SearchTalos Constraint ParserTalos Semantic Engine Result
tv stand for 75 inch tv0 results (or unrelated popular-products fallback grid)Category: Media Stand · Width ≥ 67" · In Stock10 matching solid-wood & oak media consoles (68"–84" W) ranked by TV-fit margin
couch that is good for kids and dogsDining chairs & counter stools matching the token "kids"Category: Sofa / Couch · Fabric: Pet-Friendly / Stain-Resistant Performance72 performance-fabric & rub-tested sofas ranked by family durability
apartment size sofa under 80 inches that isn’t leather88" and 94" leather sectionals (ignores "< 80" and negation "isn’t")Category: Sofa · Width ≤ 80" · Material ≠ Leather14 fabric & bouclé apartment sofas (68"–79" W) with zero leather leakage

From Free Score to Audit & Build

Your 60-second score and 24-hour Principal-Verified Snapshot pinpoint where your catalog and search leak demand. Next, commission a Tier 1 Search Findability Audit ($3,500 / $7,500) or Combined Search & AI Findability Audit ($5,000 / $10,000)—with 100% of the audit fee credited toward a Tier 2 Semantic Search or Catalog Build within 60 days.

$2,500 design-partner rate available for the first 3 Tier 1 Search Audits in exchange for named before/after case study rights.

If you saw our scanner in your logs

Our scanner identifies itself as RankTalos-FindabilityCheck/1.0. It reads public pages only, follows robots.txt, sends at most 60 requests one at a time with pauses, and never logs in, adds to cart, or submits forms.

To opt out, disallow RankTalos-FindabilityCheck/1.0 in robots.txt or email hello@ranktalos.com and we will add your domain to our opt-out list. See our findings policy and responsible disclosure.

About the Findability Score

What does the RankTalos Findability Score test in 60 seconds? It reads your public catalog, generates 8 catalog-grounded natural-language requests where at least 2 in-stock products match, runs them on your live search API, checks schema.org/Product JSON-LD and AI crawler rules, and computes four engineering sub-scores (0–100): Semantic & Constraint Recall (30%), Ranking Precision & Honesty (15%), Catalog Attribute Coverage (30%), and AI Crawler & Schema Readiness (25%).

How does the Engine Confidence Badge work? If your store runs Shopify Native Search, Fast Simon, or Constructor, the scanner queries the exact live search API shoppers see and prints a High Confidence badge. If we detect a third-party JS widget (Klevu, Searchspring, Boost) or non-Shopify stack, the report displays a "Partial — JS Widget Detected" badge, scores Catalog Attribute Coverage and AI Readiness live, and offers a free 24-hour Principal-Verified Snapshot of your live search widget.

How does the Talos Semantic Search side-by-side preview work? For failed constraint queries, your report shows what your current search returned alongside the exact in-stock products from your catalog matched by our Talos Semantic Engine constraint parser (plus a link to our live 10,000-SKU reference showcase at usafurnish.com).

Will it slow down my store? No. It sends at most 60 polite requests, one at a time with 400–700ms pauses, identifies itself as RankTalos-FindabilityCheck/1.0, and strictly follows your robots.txt.

Where does the revenue-at-risk figure come from? Online revenue × 44% from shoppers who search × natural-language share of searches × measured failure rate (45% in our furniture study, replaced by your store’s own measured failure rate) × 53% who leave after a failed search: about $210K to $525K per $10M of online revenue.